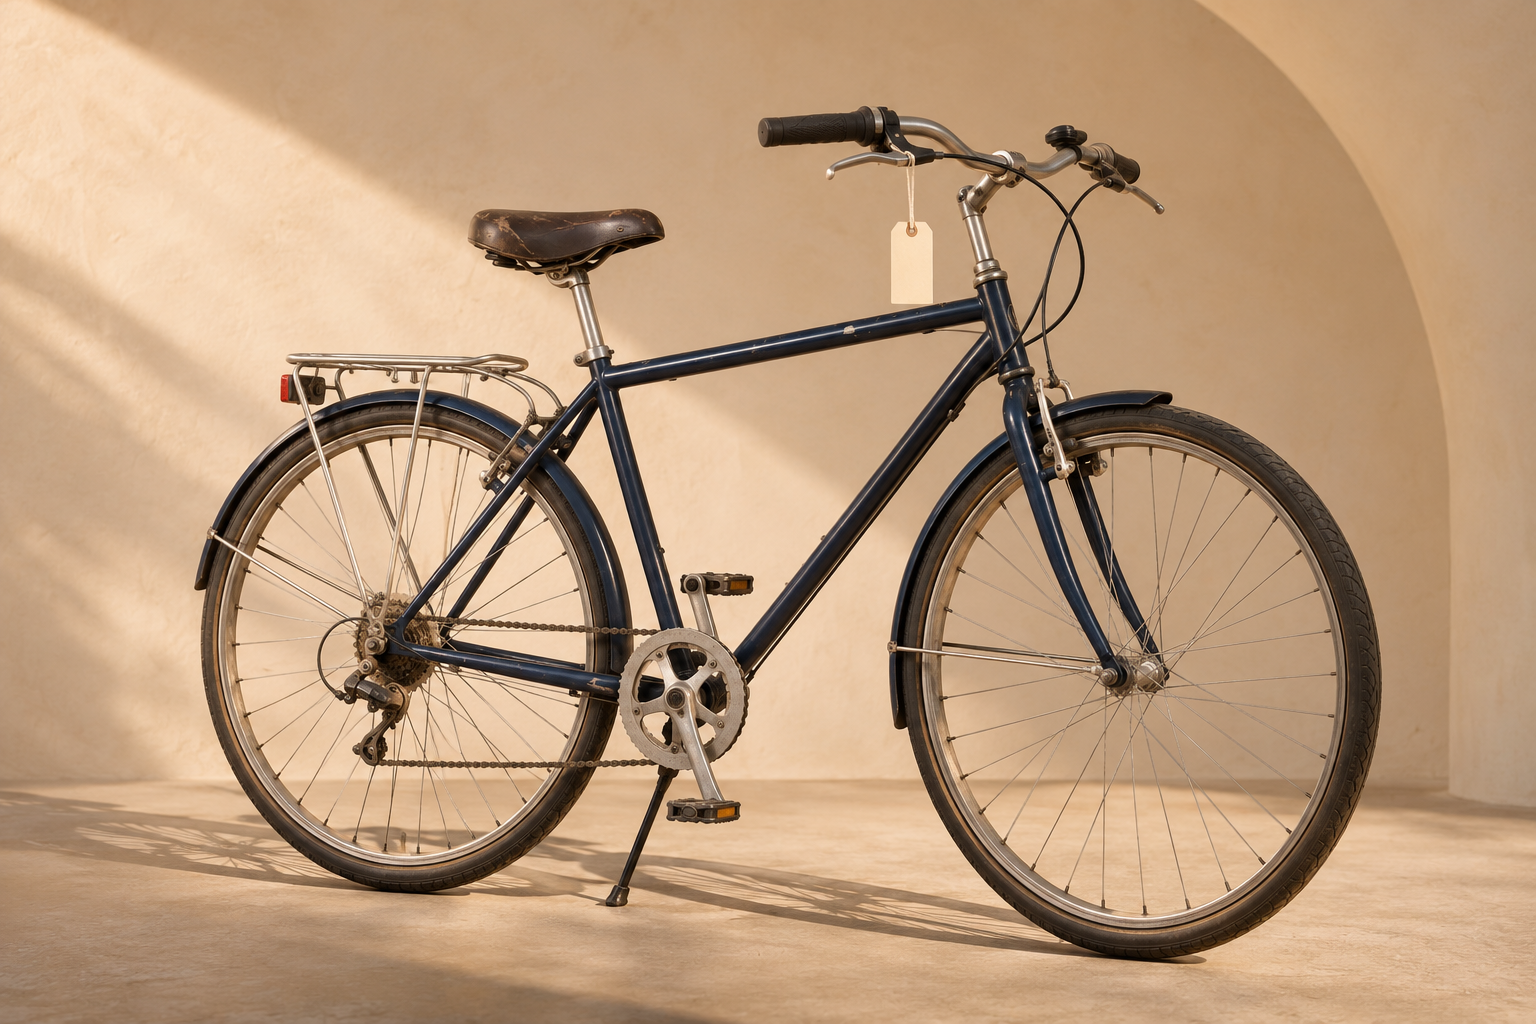
You want to sell a bike you no longer use. You give a chat app three facts: “Blue city bike. Seven gears. Used for two years.” Then you ask for a short listing.
It might produce: “For sale: a blue city bike with seven gears, used for two years.” Ask it to sound friendlier, and the wording changes. Did the app find that sentence somewhere, or create it as it went?
This fictional example shows three short facts becoming a new sentence.
A ready-made listing or a new draft?
A text-generating language model’s basic job is not to search the internet for a ready-made listing on every request. It can use relationships learned during training to produce a continuation suited to the input. An app may also search; searching and generating text are different operations.
A digit-recognition model predicts which digit an image represents. This model uses predictions about how text could continue. Both learn from examples, but they perform different tasks.
Systems that create content such as text, images or audio come under the umbrella of . Here, we’re looking at language models that generate text piece by piece; image and audio systems don’t all work the same way.
A is an AI model trained on extensive collections of text. During training, it learns relationships in how words and expressions are used. These relationships are reflected in numerical settings called parameters. “Large” refers to the scale of the model, not the length of its answers or a promise that they are correct. The abbreviation is LLM.
In the bike example, the model can use your details to draft a listing. It has not seen the bike or checked its condition. The chat app uses the model and may add separate features such as search or file reading.
Text develops in small pieces
During training, a model encounters more than isolated words. It learns patterns in how words relate across texts. This helps explain how it can write a listing differently from a poem, or a friendly message differently from a formal statement.
During generation, probabilities are calculated for the next small piece of text. A selected piece is added, and the following step takes account of the text produced so far. Repeating this builds a sentence. It isn’t simply looking at the last word each time.
The small units a model uses to process text are called . A token can be a whole word, part of a word or a punctuation mark.
“Blue city bike” looks like three words to us. A model may process them as a different number of pieces; we cannot give an exact token count without knowing the model. It represents these pieces numerically. When generating an answer, it adds a piece, then calculates what comes next using the text so far and the supplied information. The sentence we see comes together through these small steps.
is the information and instructions available to the model for this response. It includes the bike being blue, having seven gears and having been used for two years, your request for a short listing, and any relevant earlier messages passed to the model.
Think of it as the notes you put in front of someone you ask to write a listing. If there is no price in the notes, the model cannot know the bike’s actual price from them. “Do not add a price; ask me if it is missing” makes your expectation clearer. Context is different from what the model learned during training; a new conversation does not automatically become permanent knowledge in the model.
When you ask for friendlier wording, the model can express the same details in a new tone. You want the wording to change; the colour, gear count and length of use should stay the same. Include all three facts in your request and compare the resulting text against them.
This is a simplified picture of how text develops, not an account of every internal calculation. The system need not select the same continuation every time. Several suitable listings can therefore emerge from the same facts.
Change the wording, keep the facts
Generating new text does not guarantee that every detail is correct or that no similar wording exists elsewhere. Familiar phrases may resemble other texts. “AI-generated” alone guarantees neither originality nor accuracy.
Suppose the listing says “recently serviced” or “scratch-free.” Both sound convincing, but neither follows from your three facts. Polished wording is not evidence of the bike’s condition.
For a two-minute experiment, give a chat app you can access the same three facts, followed by this request:
Using only my facts, write a sales listing of no more than 30 words. Don’t add a price, condition or other features. Produce a plain version, then a friendlier one.
Compare them. Have the colour, gear count and length of use stayed the same? Has only the wording changed, or has a new claim appeared? No personal information is needed. You can also write two drafts yourself and apply the same check.
The useful habit is to assess wording and factual content separately. A draft that reads well still needs both checks.
A sentence is often built progressively from context, rather than taken from a shelf. Why can a wrong detail sound so confident? Next, we’ll explore that and practical ways to check an answer.
Sources
This is your personal note, not a comment or a message to us. It is stored only for this site on this device and browser; it is not sent to a server, analytics system or AI service. Clearing browser data may erase it; it does not sync across devices.